Organizations often respond to connectivity risk by ordering a second service. That may be useful, but a second invoice, carrier name, or product label does not by itself show that the design reduces the same failure risks as the primary connection. Two services can share a conduit, building entry, facility, upstream dependency, power source, or other common point of failure.
A meaningful backup review begins with the business consequence and follows the dependencies. The purpose is not to assume that every site needs the same architecture. It is to help the organization ask better questions before describing a connection as diverse or resilient.
List the workflows that cannot wait for the primary service to return. Depending on the operation, that may include voice, point-of-sale, cloud access, security, production data, guest service, ticketing, or live broadcast traffic. Define what ‘continue’ means. Some workflows may require full performance; others may tolerate a reduced mode for a limited period.
Map the known path and dependencies for the primary and proposed backup. Ask about physical routes, facilities, upstream networks, building entries, on-site equipment, and power. The map does not need to be a perfect engineering diagram to be useful. It needs to make shared assumptions visible so the technical owner can validate them.
Do the services enter the building at the same point?
Do they share conduit, facilities, upstream providers, equipment, or power?
Would one construction incident, utility event, or equipment failure affect both?
Which dependencies are known, and which still require verification?
The organization should define the expected failover behavior instead of assuming it. Which applications move? How quickly? Is the change automatic or manual? Who receives an alert? What evidence confirms that the backup is carrying the intended traffic? The appropriate answers depend on the site and design and require technical validation.
A backup that is never validated remains an assumption. Establish a safe test method, owner, evidence record, escalation path, and review cadence appropriate to the environment. Testing should confirm not only that a circuit is present but that the priority workflows behave as expected and that the team knows what to do.
Recovery is part of the plan. Document how the service returns to normal, who verifies the applications, and how the organization records what happened. This closes the loop and helps improve the design after a real event or controlled test.
Proof in Context
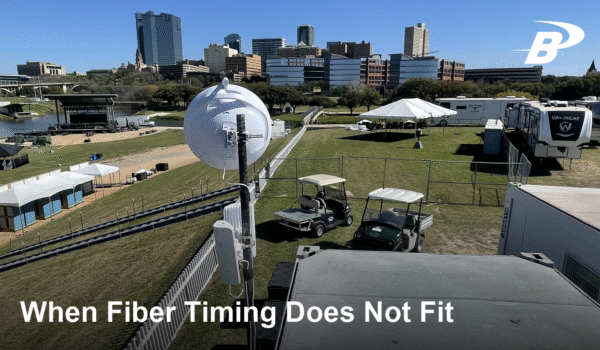
BelWave’s approved PBR case study provides one example of a designed environment. When nearby construction severed 160 fiber strands before a live event, the documented network rerouted traffic to a geographically diverse secondary path. The live broadcast, ticketing, concessions, and venue operations recorded zero minutes of downtime. That outcome belongs to that specific implementation; it is not a universal guarantee. Its useful lesson is that critical traffic, diverse dependencies, monitoring, and recovery should be planned before the event begins.
Turn Backup Into an Operating Practice
Resilience is not created by provider count alone. It comes from understanding the business consequence, validating shared dependencies, defining expected behavior, assigning ownership, and testing the plan. BelWave can help frame a site-specific resilience and serviceability conversation for organizations with a real North Texas location and operating requirement.